This post is a continuation on “Setup n8n on Kubernetes”, so most of the things we talk here assume that you’ve followed/read this one as well.
You have your own n8n instance running in Kubernetes, taking advantage of all amazing functionality and capabilities of it, but you are still going in blind right now. I mean, how can you check if your service is healthy? Is it running? How much memory is it using? 🤔
Since version @0.111.0 n8n has the ability to expose its metrics from a "/metrics" endpoint. This is great because with that we can setup a Grafana dashboard, reading from a Prometheus data source, which scrapes all containers in our Kubernetes cluster emitting metrics from, you guess it, a "/metrics" endpoint 😁.
If you want to check how we’ve done that, feel free: https://github.com/n8n-io/n8n/pull/1515
So, as the documentation explains, we just need to update our n8n configuration to have the following extra environment variable:
 1# On our ~/k8s/n8n-configmap.yaml
 2---
 3apiVersion: v1
 4kind: ConfigMap
 5metadata:
 6  name: n8n-configmap
 7  namespace: default
 8  labels:
 9    app: n8n
10    component: configmap
11data:
12  NODE_ENV: "production"
13  (...)
14  # Emit metrics from n8n service
15  N8N_METRICS: "true"
And restart our n8n deployment so these changes take effect:
1$ kubectl rollout restart deployment n8n-deployment
There are other options related to how n8n can emit metrics, which you can check here: https://docs.n8n.io/reference/configuration.html#prometheus
If we go again to your browser and check the “/metrics” endpoint, we should see something like this:
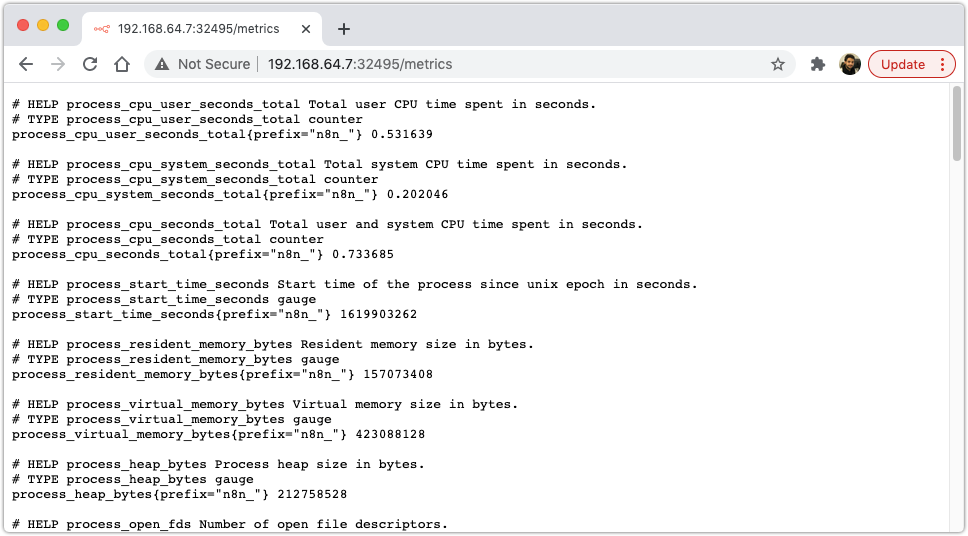
This by itself is not that useful… although, we can go a step forward and setup a dashboard with this information. 🚀
Show in Grafana
We will save ourselves some time and just use helm, which basically is a package manager for Kubernetes. It helps us with installing most of what we need to make this work.
To install it, we can just run this:
1$ brew install helm
For this example we will install both Grafana and Prometheus, but in a different namespace just so we don’t end up with to much stuff on our default one (it’s also good practice to create different namespaces for specific use cases 🙌 ).
1$ kubectl create namespace monitoring
2namespace/monitoring created
Install Grafana + Prometheus helm charts
Following Prometheus installation guide we can just add the corresponding helm charts and install our requirements:
1$ helm repo add prometheus-community https://prometheus-community.github.io/helm-charts
2$ helm repo add grafana https://grafana.github.io/helm-charts
3$ helm -n monitoring install prometheus prometheus-community/prometheus
4$ helm -n monitoring install grafana grafana/grafana
To check that everything is up and running, we can just kubectl get all, like so:
 1$ kubectl -n monitoring get all
 2NAME                                                 READY   STATUS    RESTARTS   AGE
 3pod/grafana-55777c78b6-9nhhp                         1/1     Running   0          18s
 4pod/prometheus-alertmanager-ccf8f68cd-5cjs7          1/2     Running   0          23s
 5pod/prometheus-kube-state-metrics-685b975bb7-z46f4   1/1     Running   0          23s
 6pod/prometheus-node-exporter-4klz5                   1/1     Running   0          23s
 7pod/prometheus-pushgateway-74cb65b858-zp8gk          1/1     Running   0          23s
 8pod/prometheus-server-d9fb67455-7pv4m                1/2     Running   0          23s
 9
10NAME                                    TYPE        CLUSTER-IP       EXTERNAL-IP   PORT(S)    AGE
11service/grafana                         ClusterIP   10.107.166.24    <none>        80/TCP     18s
12service/prometheus-alertmanager         ClusterIP   10.100.52.188    <none>        80/TCP     23s
13service/prometheus-kube-state-metrics   ClusterIP   10.98.71.76      <none>        8080/TCP   23s
14service/prometheus-node-exporter        ClusterIP   None             <none>        9100/TCP   23s
15service/prometheus-pushgateway          ClusterIP   10.104.143.114   <none>        9091/TCP   23s
16service/prometheus-server               ClusterIP   10.111.230.177   <none>        80/TCP     23s
17
18NAME                                      DESIRED   CURRENT   READY   UP-TO-DATE   AVAILABLE   NODE SELECTOR   AGE
19daemonset.apps/prometheus-node-exporter   1         1         1       1            1           <none>          23s
20
21NAME                                            READY   UP-TO-DATE   AVAILABLE   AGE
22deployment.apps/grafana                         1/1     1            1           18s
23deployment.apps/prometheus-alertmanager         0/1     1            0           23s
24deployment.apps/prometheus-kube-state-metrics   1/1     1            1           23s
25deployment.apps/prometheus-pushgateway          1/1     1            1           23s
26deployment.apps/prometheus-server               0/1     1            0           23s
27
28NAME                                                       DESIRED   CURRENT   READY   AGE
29replicaset.apps/grafana-55777c78b6                         1         1         1       18s
30replicaset.apps/prometheus-alertmanager-ccf8f68cd          1         1         0       23s
31replicaset.apps/prometheus-kube-state-metrics-685b975bb7   1         1         1       23s
32replicaset.apps/prometheus-pushgateway-74cb65b858          1         1         1       23s
33replicaset.apps/prometheus-server-d9fb67455                1         1         0       23s
Exposing Grafana Dashboard
So right now both our services are not exposed. For example, in order for us to access Grafana we need to port-forward to the service:
1$ kubectl -n monitoring port-forward services/grafana 8000:80
2Forwarding from 127.0.0.1:8000 -> 3000
3Forwarding from [::1]:8000 -> 3000
4Handling connection for 8000
Instead, we can just change our service type form ClusterIP to NodePort.
If you want to understand better what types of Kubernetes services exist, this blogpost explains it perfectly!
There are a couple ways to get this done, we can:
1️⃣ Create a new service which has type NodePort
With this solution we end up with two services;
1$ kubectl -n monitoring expose deployment grafana --type=NodePort --target-port=9090 --name new-grafana
2service/new-grafana exposed
3
4$ kubectl -n monitoring get services | grep grafana
5grafana                         ClusterIP   10.105.124.167   <none>        80/TCP                        20m
6new-grafana                     NodePort    10.109.115.231   <none>        80:30361/TCP,3000:31399/TCP   2m43s
2️⃣ Delete and create a new one;
1$ kubectl -n monitoring delete service grafana
2service "grafana" deleted
3
4$ kubectl -n monitoring expose deployment grafana --type=NodePort --target-port=9090
5service/grafana exposed
6
7$ kubectl -n monitoring get services | grep grafana
8grafana                         NodePort    10.104.74.196    <none>        80:30287/TCP,3000:32521/TCP   11s
3️⃣ Update the existing one.
Which I’ve end up preferring:
1$ kubectl -n monitoring patch service grafana -p '{"spec": {"type": "NodePort"}}'
2service/grafana patched
3
4$ kubectl -n monitoring get services | grep NodePort
5grafana                         NodePort    10.107.166.24    <none>        80:30732/TCP   45s
This means that we now have a dedicated port on our host machine to access these services:
1$ minikube -n monitoring service grafana
2|------------|---------|-------------|---------------------------|
3| NAMESPACE  |  NAME   | TARGET PORT |            URL            |
4|------------|---------|-------------|---------------------------|
5| monitoring | grafana | service/80  | http://192.168.64.7:30732 |
6|------------|---------|-------------|---------------------------|
7🎉  Opening service monitoring/grafana in default browser...
Connecting Grafana to Prometheus data source
Finally, we just need to configure Grafana to use Prometheus as its main data source.
Here we are just following the tutorial on Prometheus documentation.
Before opening Grafana we need to get the admin account password, which we can do by running:
1$ kubectl -n monitoring get secret grafana -o json | jq -r '.data["admin-password"]' | base64 --decode ; echo
2SUuhmONZtGtCCCqHkMQnIz6H2NLB7k12muqiMtbw
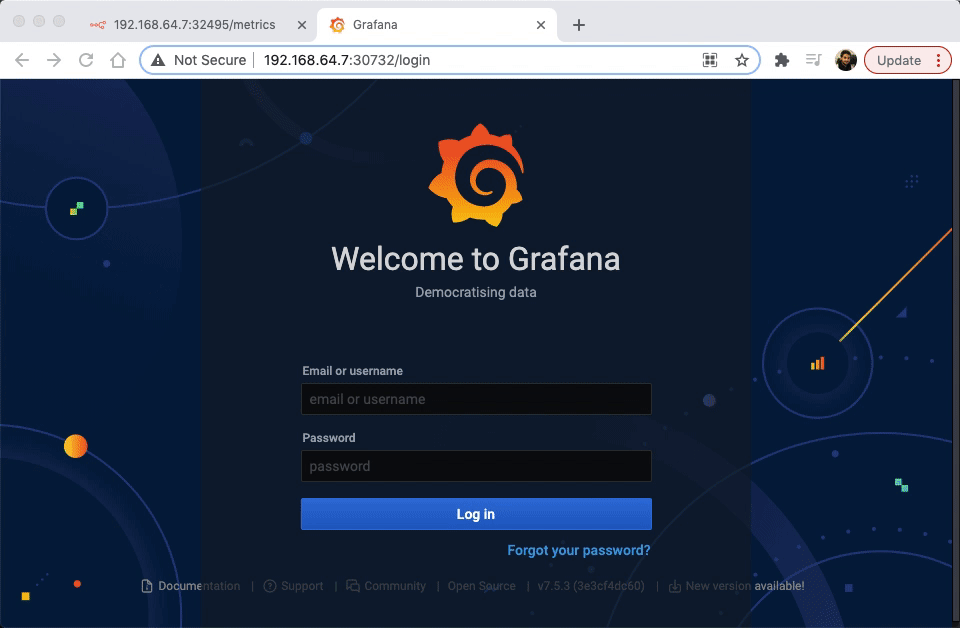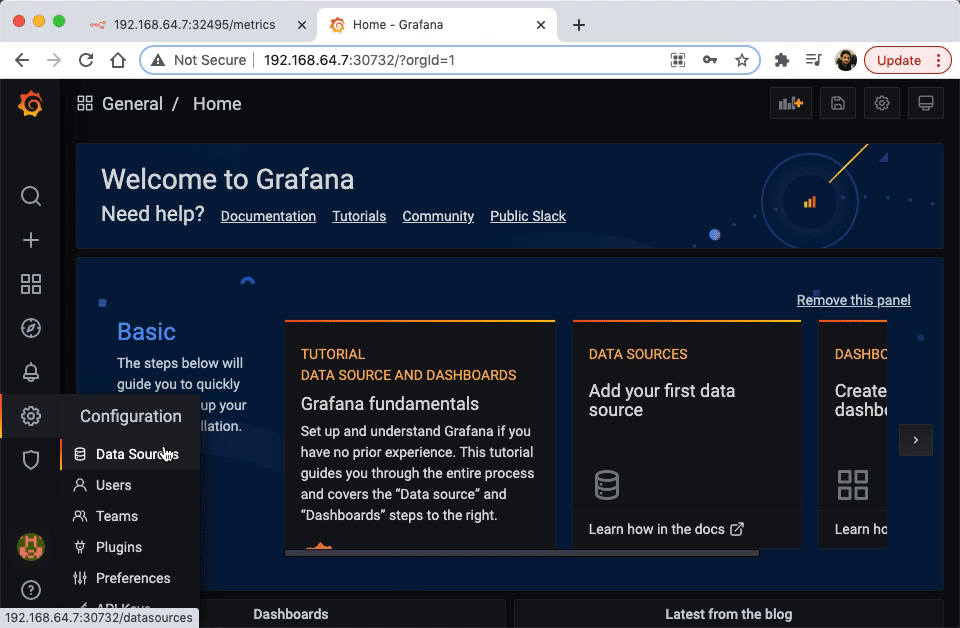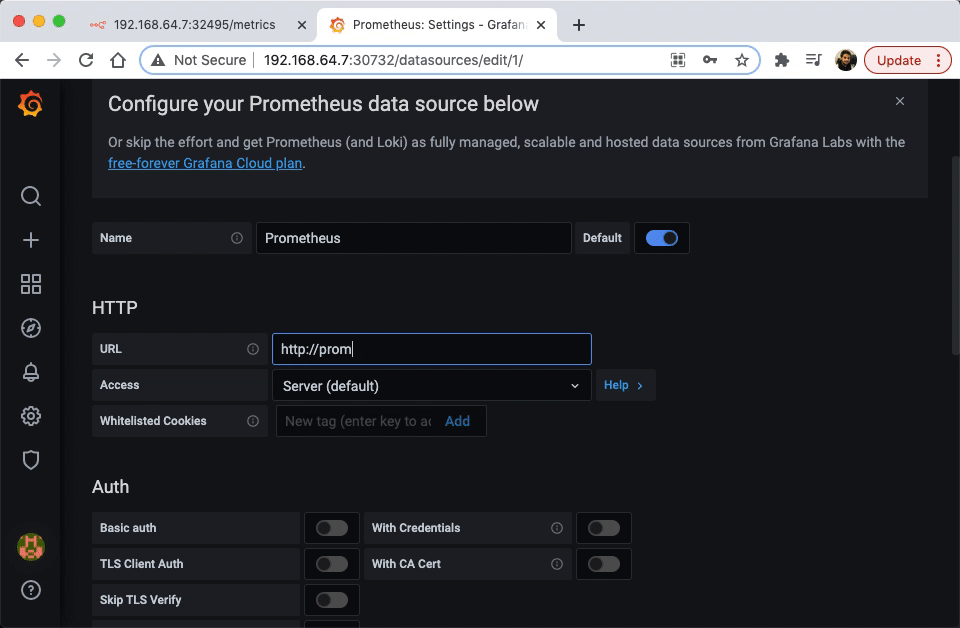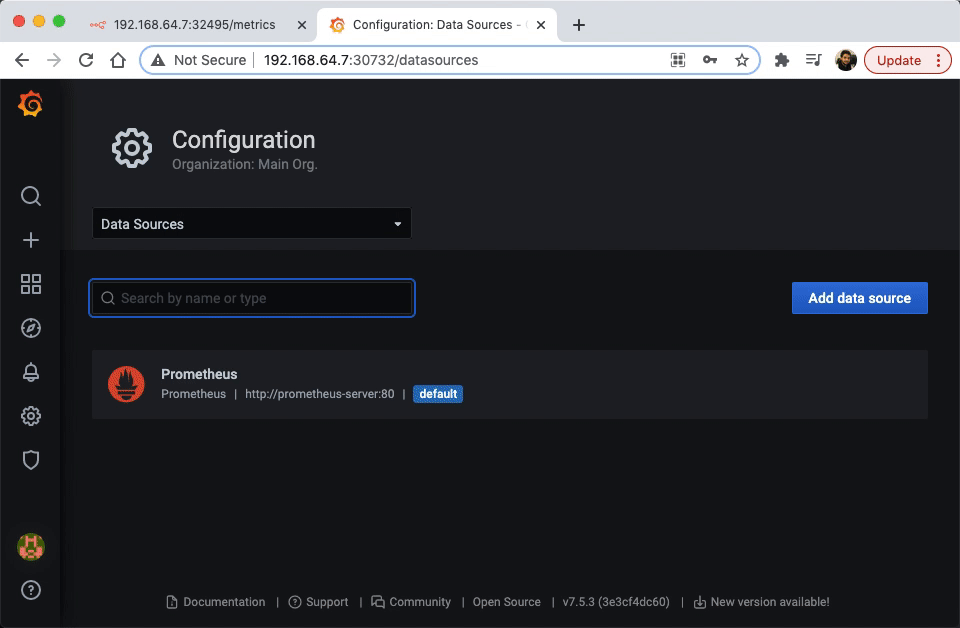
Create n8n Dashboard
Since n8n runs on top of NodeJS, we should be able to just use any Grafana dashboard that shows metrics for NodeJS servers.
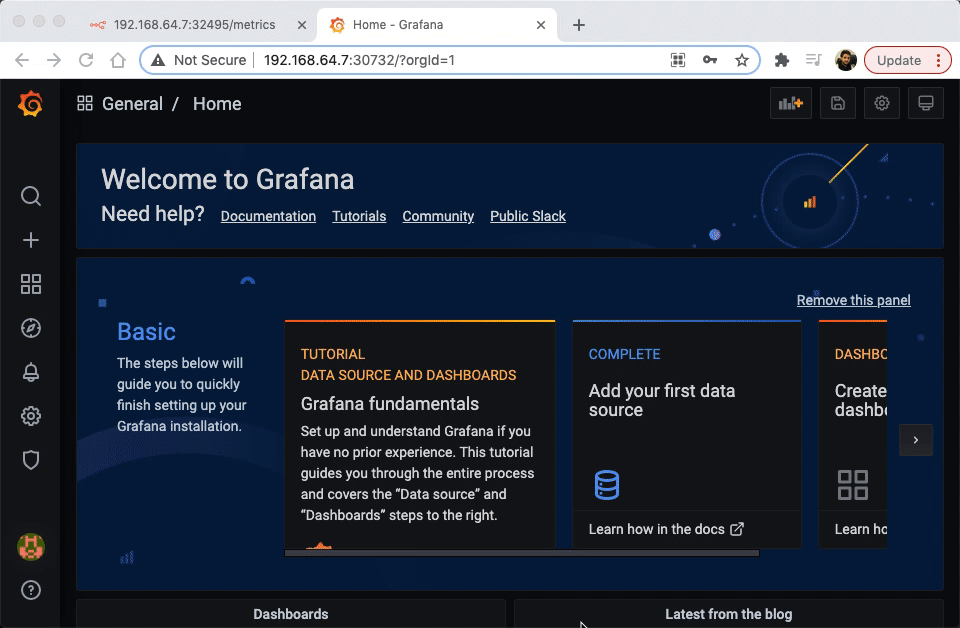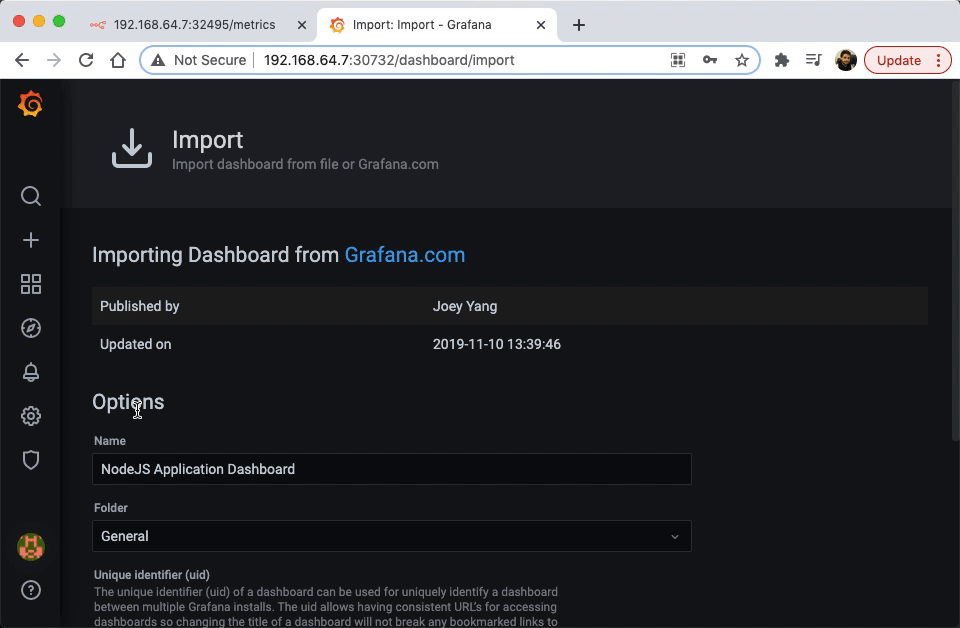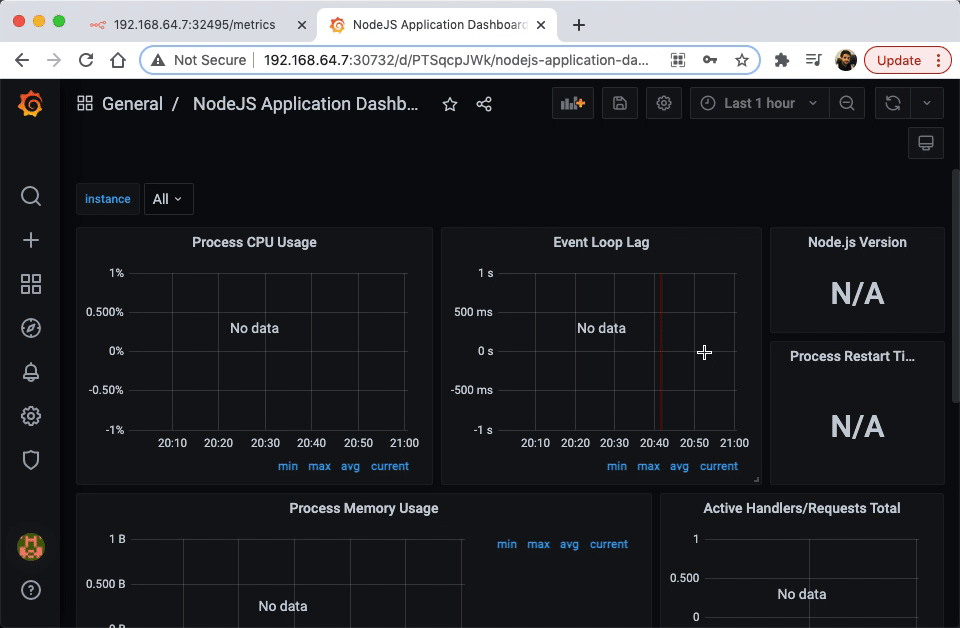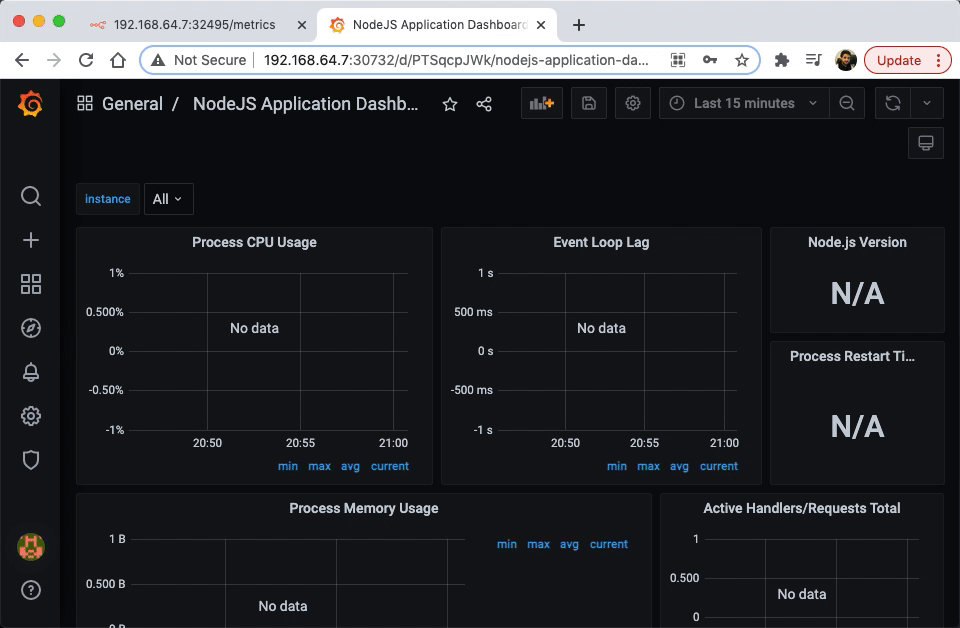
I’ve end up using the most downloaded one on Grafana’s dashboards directory, with some extra widgets.
To install the base dashboard, we just need to import it either by the URL (https://grafana.com/grafana/dashboards/11159) or Dashboard ID (11159):
You might wonder why we don’t have any metrics showing up… well, the way Prometheus works is by scrapping (pulling) data from the “/metrics” endpoint of a pod, but Prometheus only knows how to find that service if we “annotate” that pod with specific parameters:
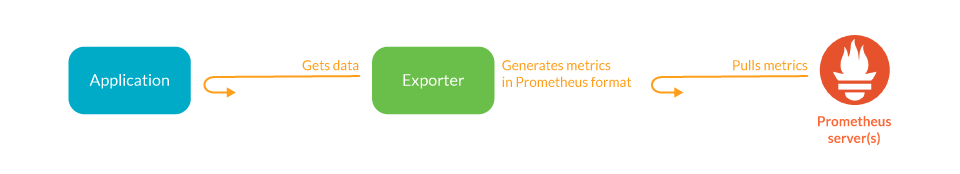
❗️ We can do it like this because the helm chart for Prometheus already had that configured out of the box. To check that in detail go here. (Image source).
So, in order for Prometheus to find our n8n container, we need to add these extra lines to our n8n-deployment.yaml configuration, and re-apply it:
 1# ~/k8s/n8n-deployment.yaml
 2---
 3apiVersion: apps/v1
 4kind: Deployment
 5metadata:
 6  name: n8n-deployment
 7  namespace: default
 8  labels: &labels
 9    app: n8n
10    component: deployment
11spec:
12  replicas: 1
13  selector:
14    matchLabels: *labels
15  template:
16    metadata:
17      labels: *labels
18      annotations:
19        prometheus.io/scrape: "true"
20        prometheus.io/path: /metrics
21        prometheus.io/port: "5678"
22    spec:
23      containers:
24      - name: n8n
25        image: n8nio/n8n:latest
26        imagePullPolicy: IfNotPresent
27 (...)1$ kubectl apply -f k8s/n8n-deployment.yaml
2deployment.apps/n8n-deployment configured
Going back to Grafana, we can see that now we have some data on our dashboards:
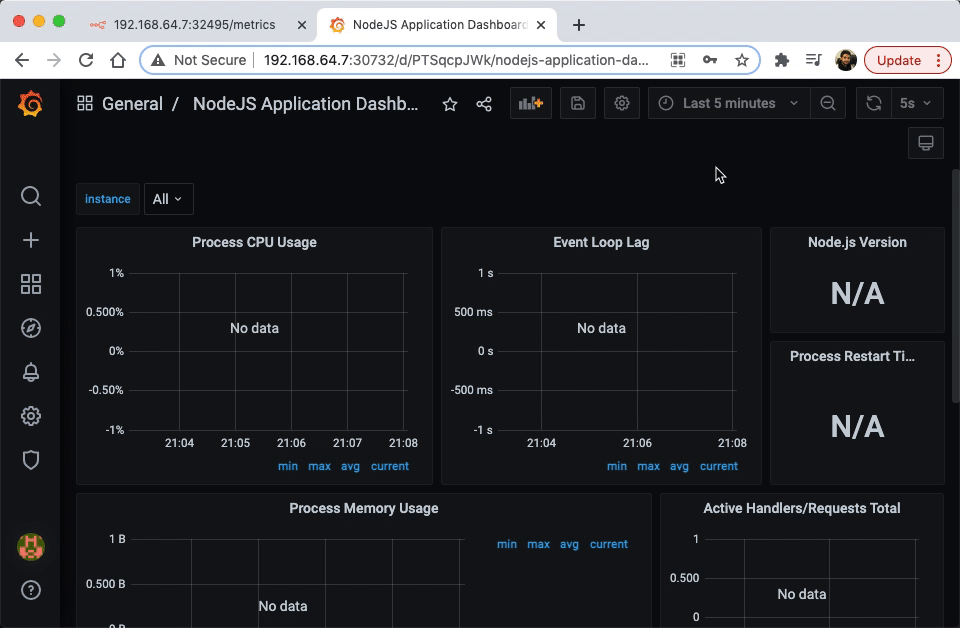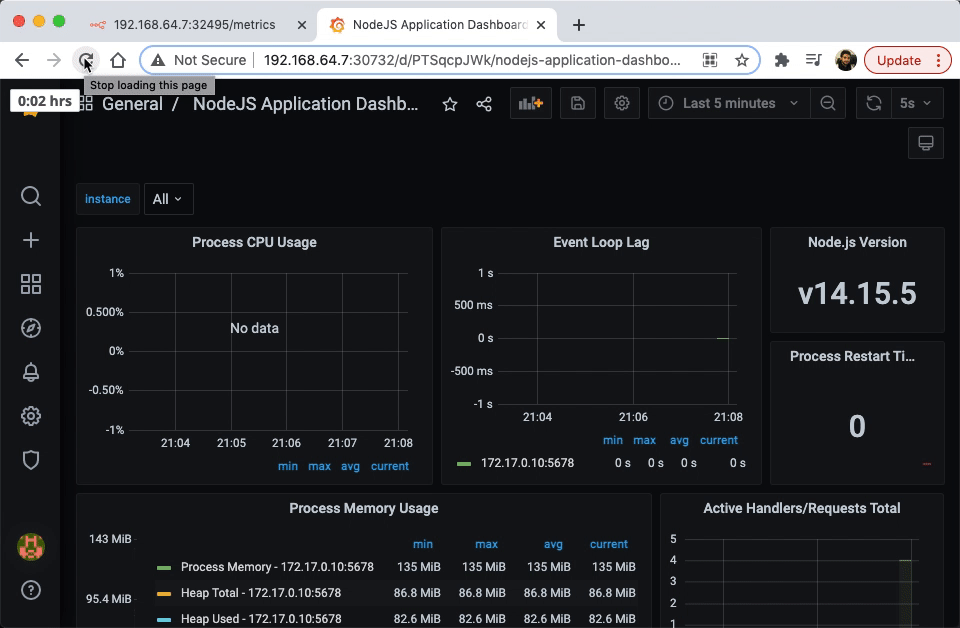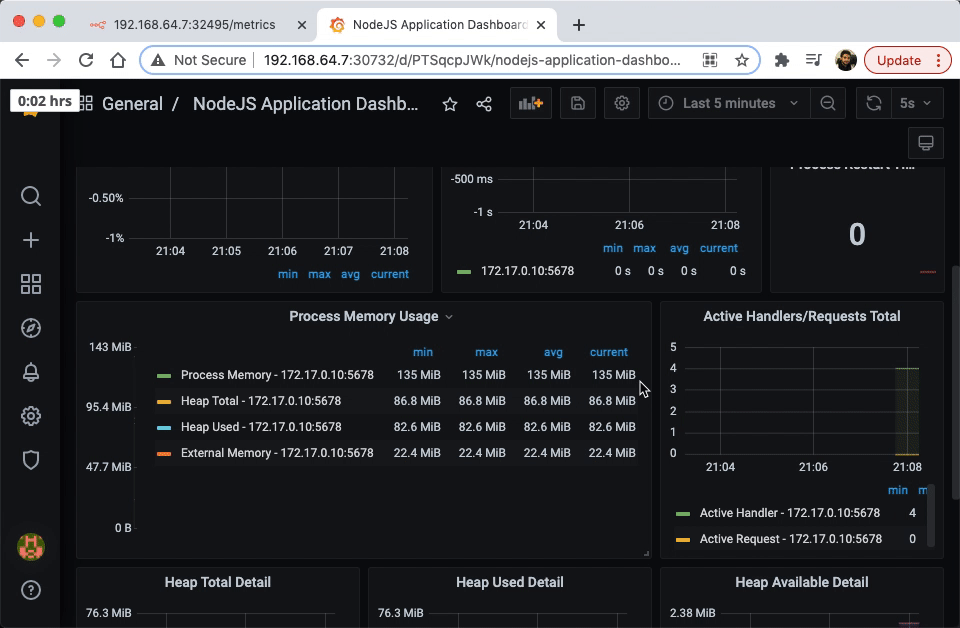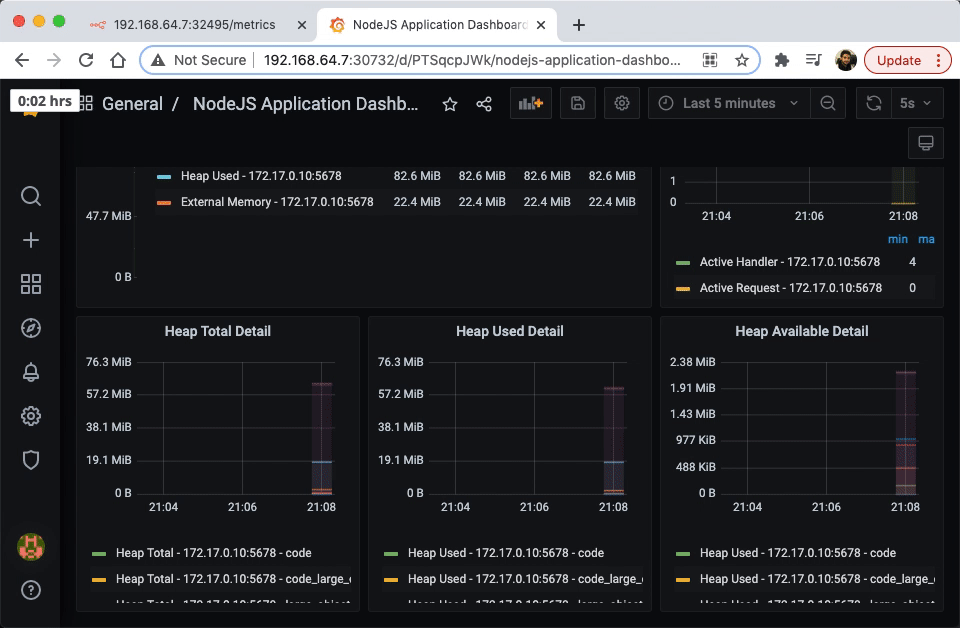
🍻
Customize your grafana dashboard
The extra dashboards that we will add we can divide them into two categories:
- Resources consumption/allocation:
- CPU used vs throttled
- Memory used by the container
- Network upload/download in transferer bytes
- Availability of our service:
- If its healthy (Up or Down)
- Historical view (99.99% of availability)
Performance and Resource consumption
CPU Usage
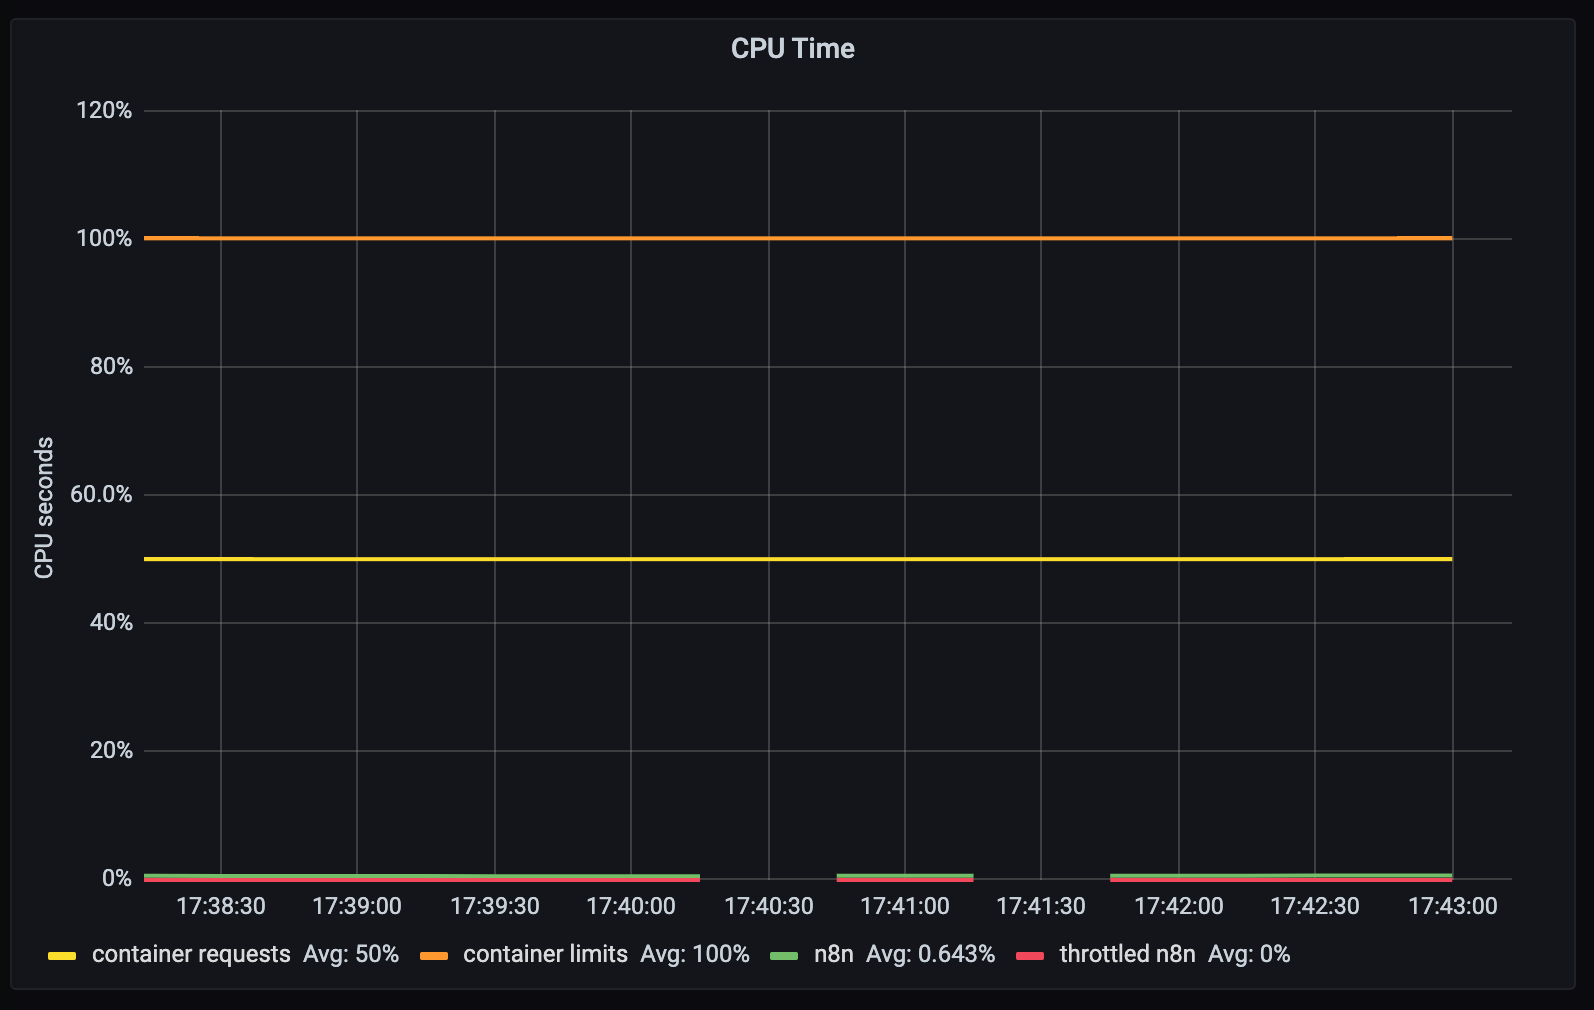
We want to show the CPU usage from our container and also if the CPU is being throttled from heavy utilization (eg: to many threads are being created for to many requests)
Also, for us to trigger alerts when we reach some % of our services capacity, we will be showing the requested container resources and limits on the dashboard. Since we asked for 1 CPU (kubernetes limit configuration) and 0.5 CPU’s (kubernetes requests configuration) we will see those two lines represented on the dashboard:
 1# cpu limits value from kubernetes container
 2avg(kube_pod_container_resource_limits_cpu_cores{namespace="default", container="n8n"})
 3
 4# cpu requests value from kubernetes container
 5avg(kube_pod_container_resource_requests_cpu_cores{namespace="default", container="n8n"})
 6
 7# container cpu usage
 8irate(container_cpu_usage_seconds_total{namespace="default", container="n8n", image!="", container!="POD"}[2m])
 9
10# container cpu throttling
11irate(container_cpu_cfs_throttled_seconds_total{namespace="default", container="n8n", image!="", container!="POD"}[2m])
And just so its easier to read at a glance, we’ll setup the colors:
- • Limit CPU resources that our container has available
- • Requested CPU resources for our container
- • CPU utilization
- • Throttled CPU utilization.
Memory allocation
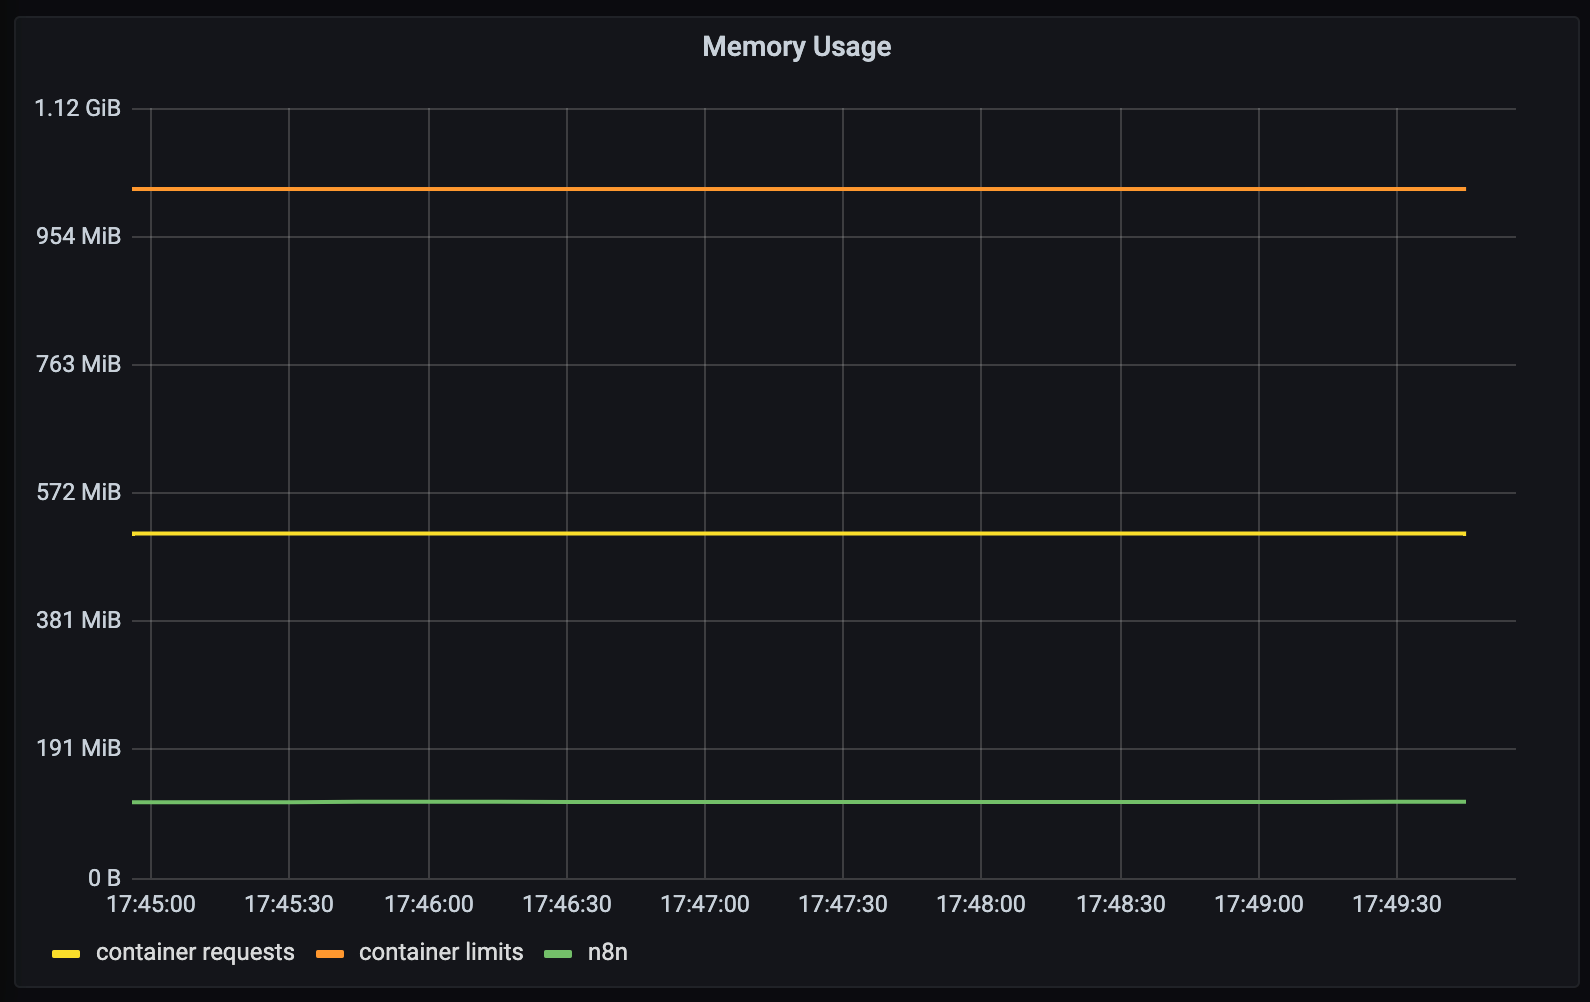
Same thing here but for memory used by the n8n container. We want to see if we are using to much memory and how is that memory being used:
- Do we have memory leaks?
- Are there processes being created which use all of our available memory?
1# memory requests value from kubernetes container
2avg(kube_pod_container_resource_requests_memory_bytes{namespace="default", container="n8n"})
3
4# memory limits value from kubernetes container
5avg(kube_pod_container_resource_limits_memory_bytes{namespace="default", container="n8n"})
6
7# container memory usage
8container_memory_working_set_bytes{namespace="default", container="n8n", image!="", container!="POD"}
Network upload/download in transferer bytes
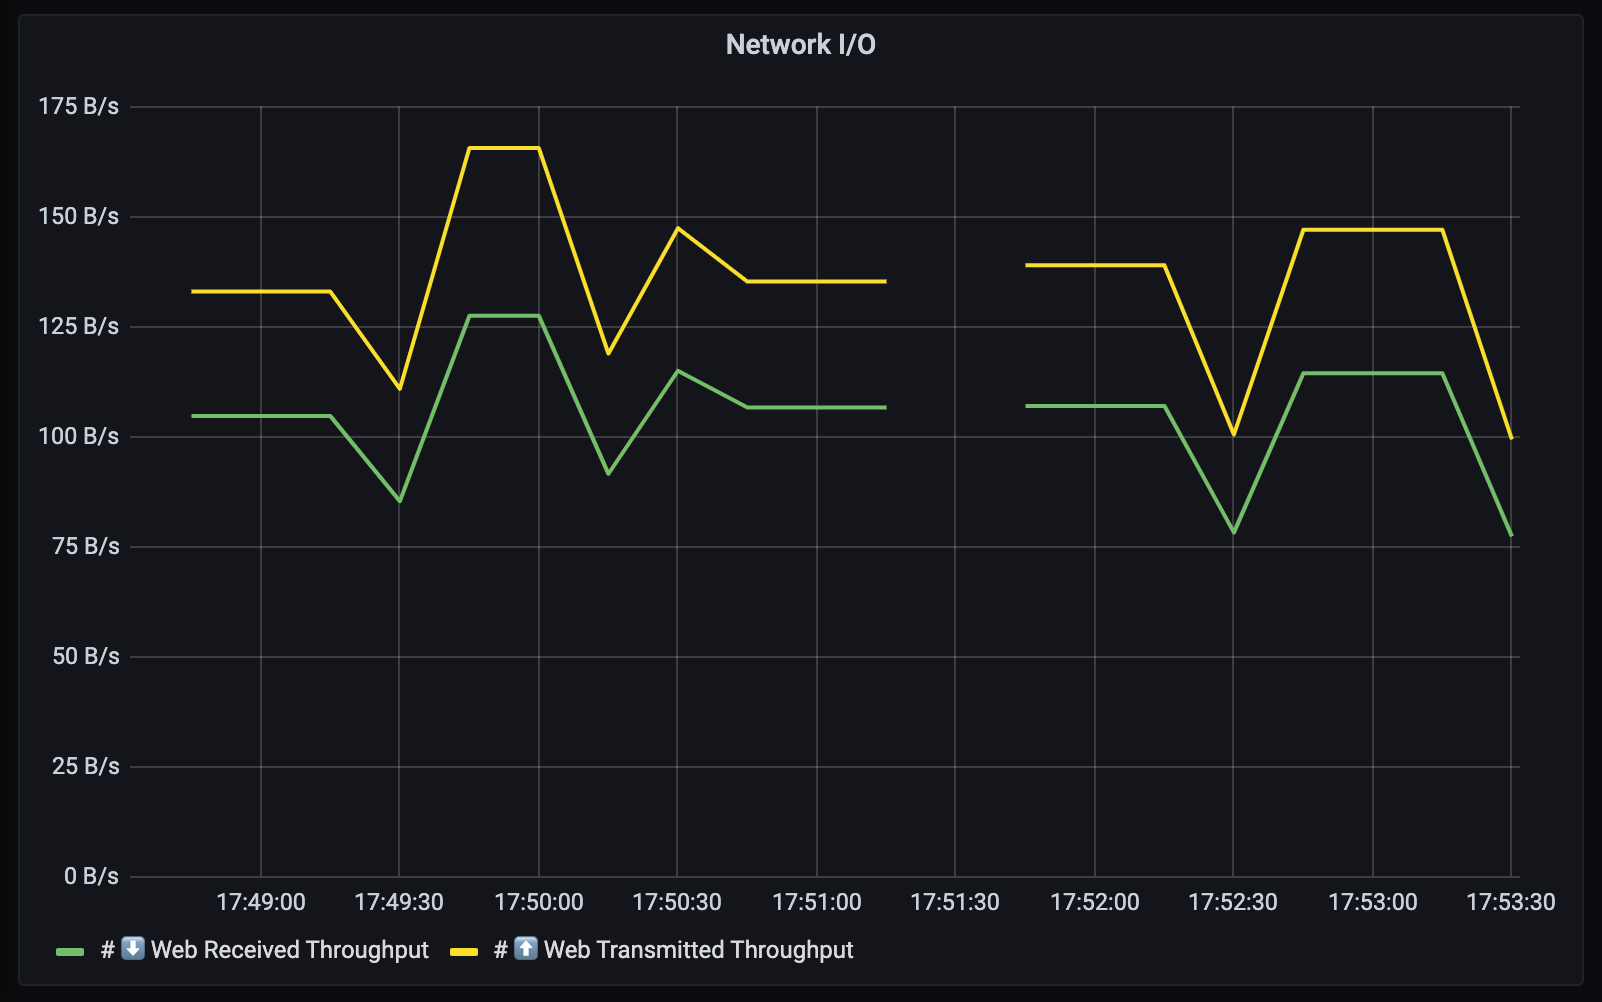
Lastly but as important, network data transfer. We want to monitor how much data we are reading and sending on the wire:
1# ⬇️ Web Received Throughput
2sum(rate(container_network_receive_bytes_total{namespace="default", pod=~"n8n-.*"}[2m]))
3
4# ⬆️ Web Transmitted Throughput
5sum(rate(container_network_transmit_bytes_total{namespace="default", pod=~"n8n-.*"}[2m]))
Availability of our service
Here we just want to check, if the service is up. A simple health check request to our server "/healthz" endpoint is enough.
n8n offers this endpoint to check if the service is up, returning a HTTP 200 OK response. (source)
We can also show how many 9’s of availability n8n has, but for that we need to install blackbox exporter.
Install Blackbox
Blackbox is a module that offers a simple API to check if a service, for a given URL is returning 200 OK. The idea is to use Prometheus to automatize this check, so we can show it on our dashboard as a nice widget.
To install it we can use again helm as we did before:
1$ helm -n monitoring install blackbox prometheus-community/prometheus-blackbox-exporter
Then to expose it to Prometheus, we just need to create a service called blackbox.
⚠️ The name is the most important part! This is how Prometheus finds the blackbox exporter service:
1$ kubectl -n monitoring expose deployment blackbox-prometheus-blackbox-exporter --port 80 --target-port=9115 --name blackbox
When we install it via helm, the service that is generated is named
{{name}}-prometheus-blackbox-exporterwhich Prometheus fails to find. I’ve spend more time than I care to admit trying to understand the inner workings of Blackbox with Prometheus, and this is the simplest solution that I could find without having to go into Prometheus and tweak its scrape configurations. If you wanna go that route, you can look at these 1, 2, 3, 4, 5. Also, you might need to understand how prometheus relabeling works or different blackbox configurations 6, 7, 8.
Cool, now that we have our blackbox probe running, we still need to update our n8n-service.yaml configuration to be “scrappable”, and this is done by adding the prometheus.io/probe annotations like so:
 1# ~/k8s/n8n-service.yaml
 2---
 3apiVersion: v1
 4kind: Service
 5metadata:
 6  name: n8n-service
 7  namespace: default
 8  annotations:
 9    prometheus.io/probe: "true"
10    prometheus.io/probe-path: "/healthz"
11  labels:
12    app: n8n
13    component: service
14spec:
15  type: NodePort
16  selector:
17    app: n8n
18    component: deployment
19  ports:
20  - protocol: TCP
21    name: http
22    port: 80
23    targetPort: 5678
😓 We’re almost there.
The default Prometheus configuration tries to check if the "/probe" endpoint of the service is returning 200 OK. This is a problem for us because we can’t override the n8n "/healthz" endpoint to “/probe”. So, the next best solution is to add this configuration to our prometheus.yaml ConfigMap.
This might feel daunting at first, but its actually pretty straightforward. We just need to edit our prometheus-service ConfigMap like so:
1$ kubectl -n monitoring edit configmap prometheus-server -o yaml
And then on the “kubernetes-services” section of the configuration, we need to append the following part that is highlighted below:
 1# ...
 2- job_name: kubernetes-services
 3  kubernetes_sd_configs:
 4  - role: service
 5  metrics_path: /probe
 6  params:
 7    module:
 8    - http_2xx
 9  relabel_configs:
10  - action: keep
11    regex: true
12    source_labels:
13    - __meta_kubernetes_service_annotation_prometheus_io_probe
14  - source_labels:
15    - __address__
16    target_label: __param_target
17  - replacement: blackbox
18    target_label: __address__
19  - source_labels:
20    - __param_target
21    target_label: instance
22  - action: labelmap
23    regex: __meta_kubernetes_service_label_(.+)
24  - source_labels:
25    - __meta_kubernetes_namespace
26    target_label: kubernetes_namespace
27  - source_labels:
28    - __meta_kubernetes_service_name
29    target_label: kubernetes_name
30  - source_labels: [__param_target, __meta_kubernetes_service_annotation_prometheus_io_probe_path]
31    separator: ';'
32    regex: (.*?);(.*?)
33    target_label: __param_target
34    replacement: ${1}${2}
35- job_name: kubernetes-pods
36# ...
This just allows us to setup, under any kubernetes Service configuration, an “prometheus.io/probe_path” annotation with a different endpoint that can replace the default
metric_path: /probe. (issue that explains this: https://github.com/prometheus/blackbox_exporter/issues/113)
Service Uptime
Lastly, we just need to create two new widgets on our dashboard: “Uptime (%)” and “Service Uptime”
1# For the "Uptime %", we need two queries that show 99.99 over a week/two week period
2avg_over_time(probe_success{app="n8n"}[7d])
3avg_over_time(probe_success{app="n8n"}[14d])
4
5# For the Service Uptime, we just want to check the `probe_success` results
6probe_success{app="n8n"}
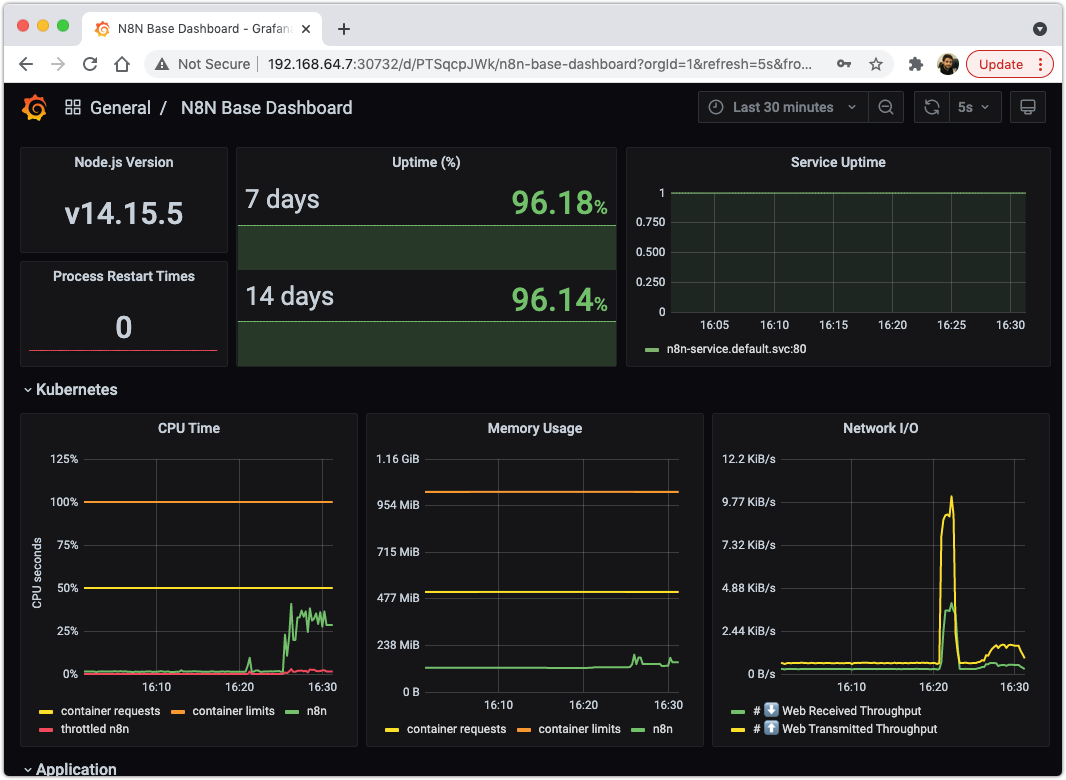
And that is all, we have a good base for our n8n dashboard in grafana 🚀.
If you want to use this dashboard you can download it here 👉 n8n-grafana-dashboard.json 👈
Resources
- Prometheus config on n8n: https://docs.n8n.io/reference/configuration.html#prometheus
- Create new namespace in Kubernetes: https://www.assistanz.com/steps-to-create-custom-namespace-in-the-kubernetes/
- Setup Prometheus + Grafana in Minikube: http://blog.marcnuri.com/prometheus-grafana-setup-minikube/
- Differences between NodePort and ClusterIP: https://medium.com/google-cloud/kubernetes-nodeport-vs-loadbalancer-vs-ingress-when-should-i-use-what-922f010849e0
- Configure Prometheus to scrape your containers “/metrics” endpoint: https://github.com/prometheus-community/helm-charts/tree/main/charts/prometheus#scraping-pod-metrics-via-annotations
- Monitoring on Kubernetes with Prometheus: https://sysdig.com/blog/kubernetes-monitoring-prometheus/
👋